

Set it up
1
Add a provider
In the OpenWork Cloud dashboard, open 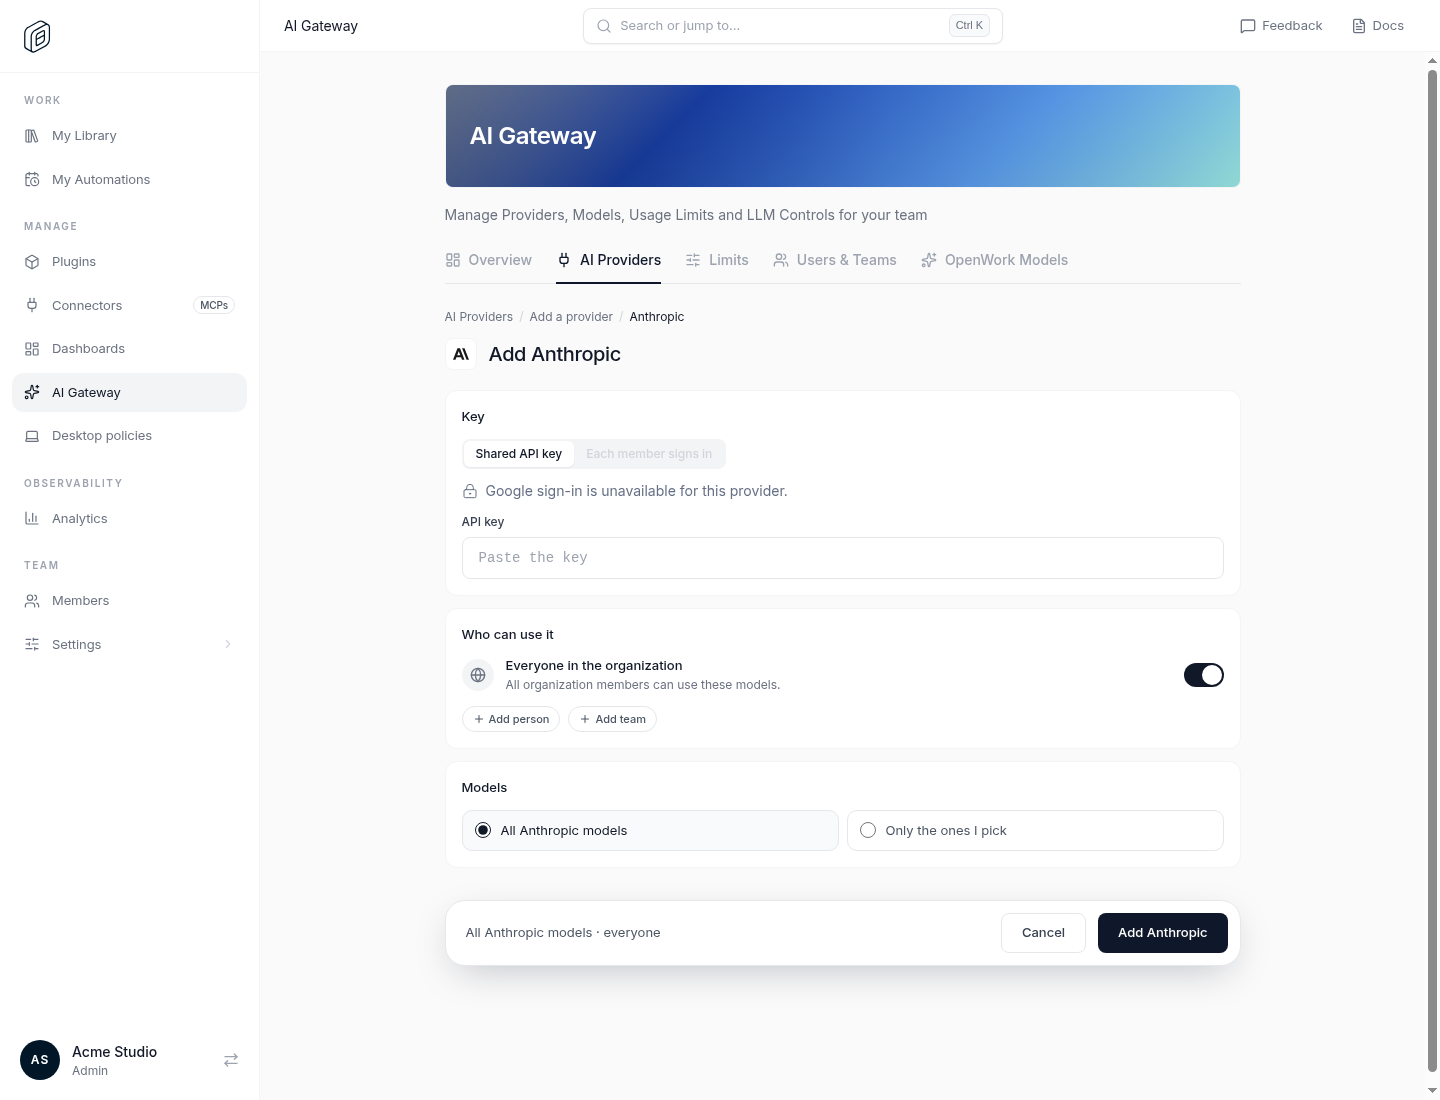
AI Gateway > AI Providers > Add provider and pick one from the catalog.2
Choose who can use it
Keep 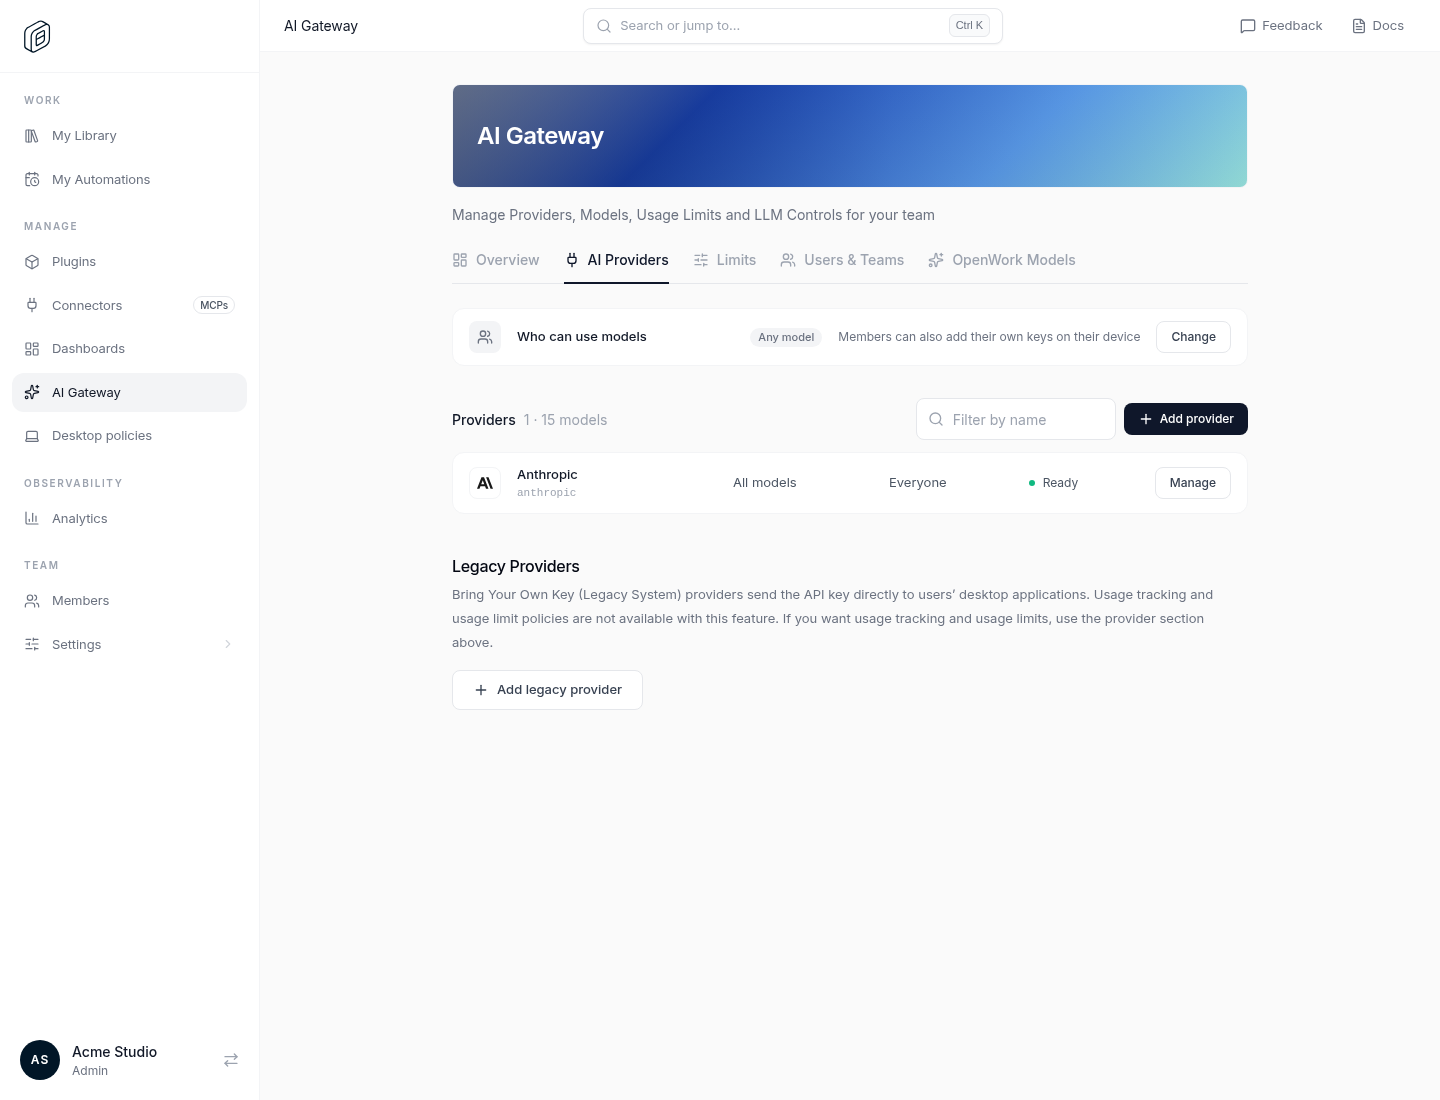
Everyone in the organization, or add specific teams and people. Pick all models or only some.3
Limit models (optional)
Under 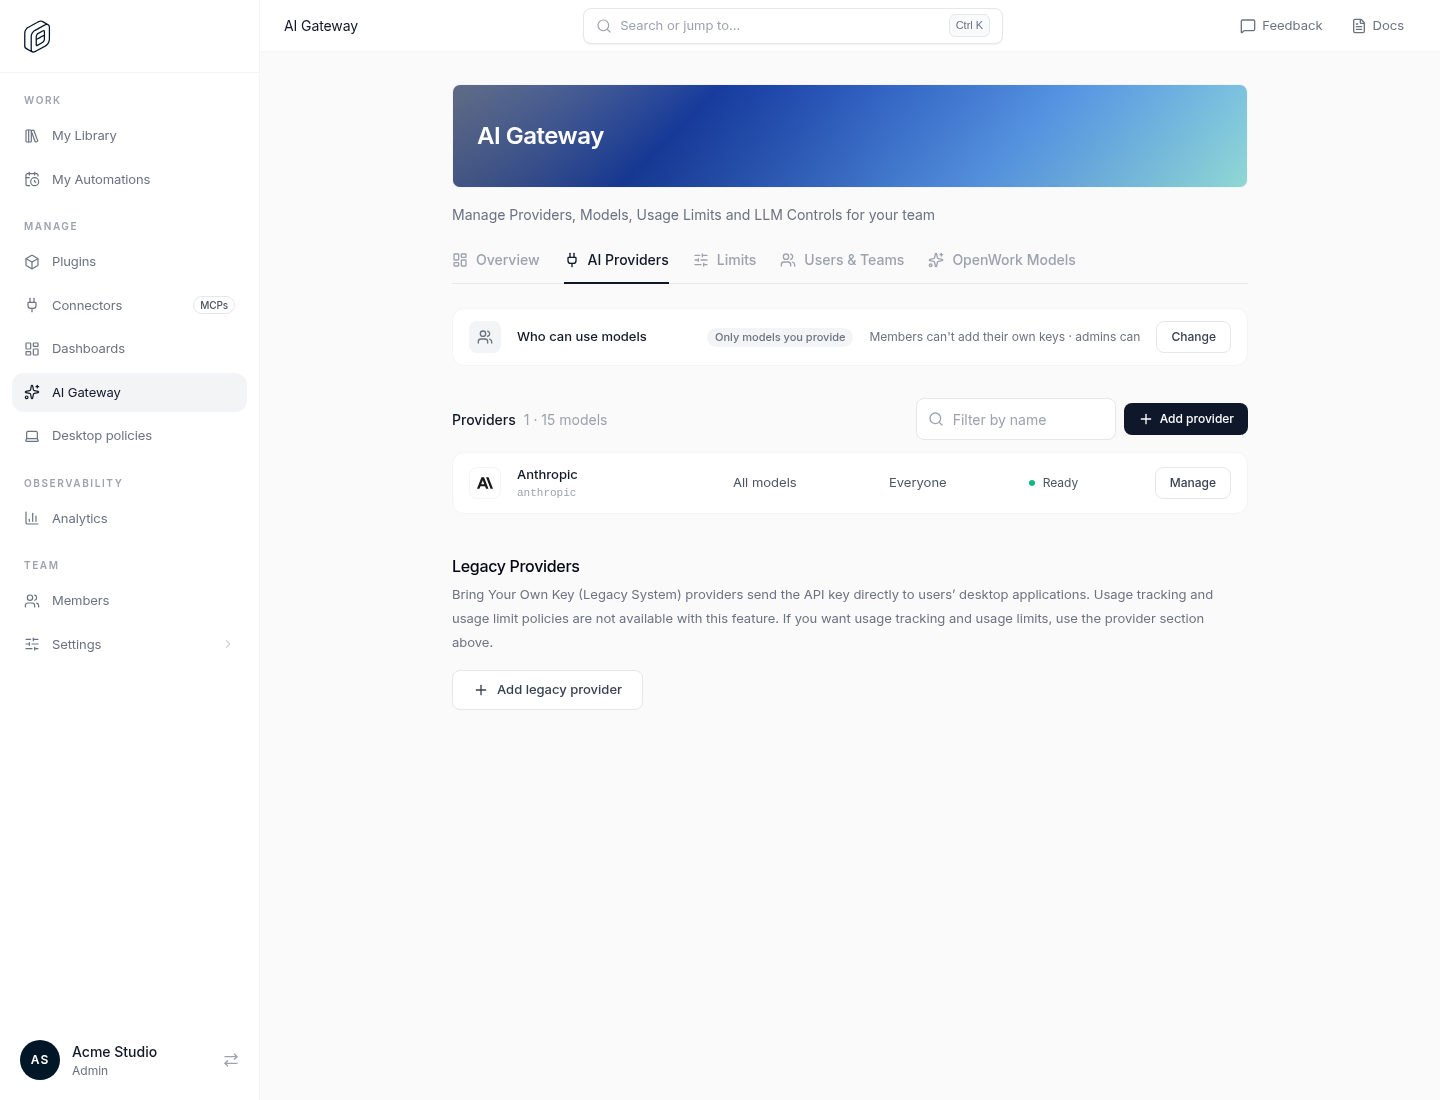
Who can use models, choose Only models you provide so members can’t add their own keys.4
Set spend limits
On 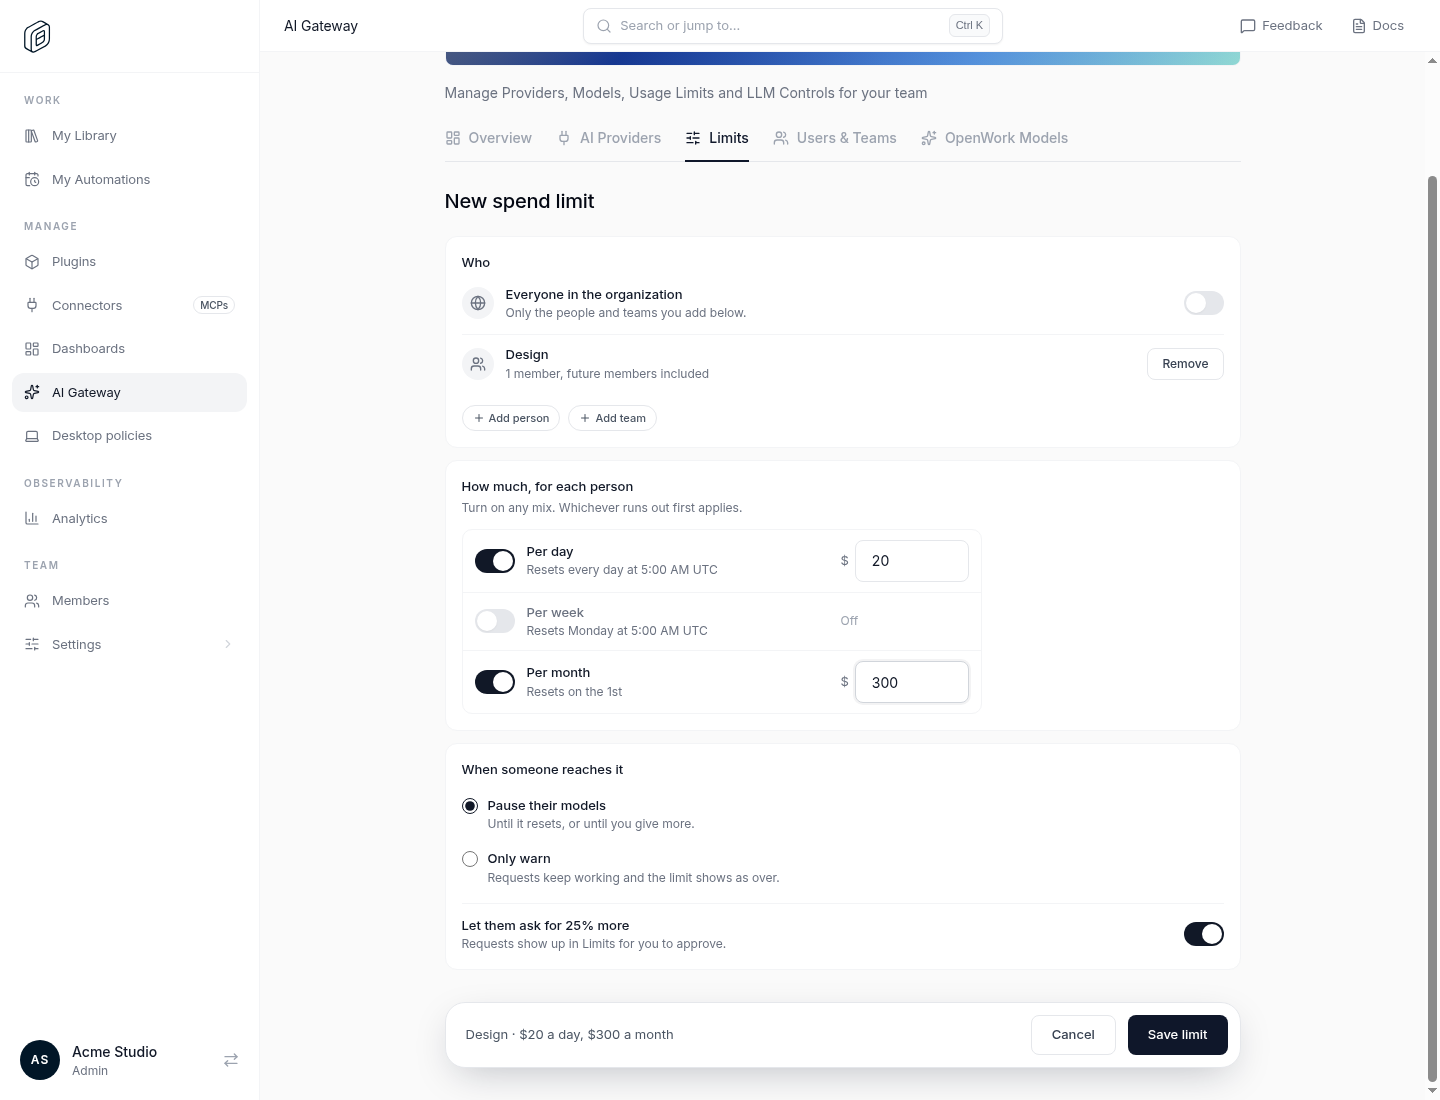
Limits, give a team or person a daily, weekly, or monthly USD amount. Pause or warn when it runs out.5
Test it
A member picks the model in the desktop app or OpenWork Web and sends a prompt. Granted models sync automatically.
What you get
Keys stay on the server
One org credential per provider, or per-member Google sign-in for Vertex AI.
Access per team
Group models, then grant each group to the org, a team, or a person.
Spend limits
USD allowances with hard limits and optional increase requests.
Usage by person
Per-member keys attribute tokens and cost. See Counting usage.
FAQ
Which providers are supported?
Which providers are supported?
OpenAI, Anthropic, Google, Google Vertex AI (including Claude on Vertex), Azure, Amazon Bedrock, Mistral, OpenRouter, and catalog providers with an OpenAI-compatible API. Models come from the models.dev catalog.
How is this different from OpenWork Models or bring your own keys?
How is this different from OpenWork Models or bring your own keys?
AI Gateway routes your providers through OpenWork with access rules, limits, and usage tracking. OpenWork Models is a managed subscription with no keys, billed separately. Bring your own keys syncs an org provider to members and the app calls it directly; see Managed LLM provider. The MCP Gateway is separate: it shares skills and connections, not models.
How accurate is the cost view?
How accurate is the cost view?
Costs are estimates from reported tokens and public prices, or a provider-reported cost when returned. They are not your provider’s bill. See Token costs.
What does it cost?
What does it cost?
Shared keys are on the Team plan and spend observability is on Enterprise, for Cloud and self-hosted alike. Providers bill model usage. See Pricing and licensing.